TL;DR

Get privacy and security gear delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
Dependency risk is the probability that something your product relies on — a library, API, vendor, or internal team — fails, delays, or changes in a way that harms delivery. This guide explains the six types of dependencies product teams face, how to map and score them, and a practical playbook for reducing their impact before they derail your roadmap.
In December 2021, a product team somewhere woke up to find their logs full of errors. Not because of their code — because a frustrated open-source maintainer had deliberately broken two tiny npm packages called colors.js and faker.js. Thousands of build pipelines froze within hours. Most affected teams had never even heard of the packages; they were three or four layers down the dependency tree.
That’s dependency risk in one image: a stranger’s weekend decision becoming your Monday incident. And it’s not just open source. It’s the mapping API that changes pricing, the platform team that’s booked until Q3, the app store policy update that arrives without warning.
This guide gives you a complete overview you can use to structure how your team thinks about dependencies — what they are, how to find the hidden ones, how to score them honestly, and what to do when they break. No fear-mongering. Just practical habits.
Dependencies — not internal capacity — are often the bigger cause of roadmap slippage, because you’re estimating your work but shipping depends on others’.
Track all six dependency types (technical, organizational, vendor, data, regulatory, market), not just the libraries and APIs you can see in your codebase.
Maintain a living dependency register and score each entry on likelihood, impact, and blast radius; revisit it quarterly.
Mitigate in three ways — reduce critical-path dependencies, add contractual and fallback protections, and decouple via abstraction layers — matched to the risk…
Watch the metrics that surface waiting: dependency count per initiative, blocked items, and the lead-time vs. cycle-time gap.
What Dependency Risk Actually Is (In Plain Terms)
Dependency risk is the probability that something your product relies on — an external team, vendor, API, library, or infrastructure component — fails, delays, or changes in a way that harms your delivery, quality, or roadmap. The key word is relies. If you can’t ship without it, and you don’t fully control it, it’s a dependency risk.
Think of your product as a dinner party. The food is your code. But the delivery van, the grocery store, and the friend bringing dessert? Those are dependencies. If any of them is late, the dinner is late — no matter how well you cooked.
Here’s the part that surprises most product managers: dependencies are frequently a bigger cause of roadmap slippage than internal capacity. Your team’s velocity might be perfectly predictable. The payments API review queue? Not so much. That’s why estimation fails so often — you’re estimating your work, but shipping depends on everyone else’s too.
And coordination cost doesn’t scale politely. According to long-standing software engineering wisdom — Brooks’s Law, Conway’s Law — overhead grows non-linearly with each dependency you add. Two dependencies aren’t twice the headache of one. They’re closer to four times.
The 6 Types of Dependencies Hiding in Your Roadmap
Most product teams only spot technical dependencies — the libraries and APIs. But dependency risk comes in at least six flavors, and the dangerous ones are usually the ones you never listed. Here’s the full set:
- Technical dependencies — third-party APIs, SDKs, open-source libraries, cloud providers, microservices owned by other teams.
- Organizational dependencies — platform teams, shared design or data teams, other product lines in your company.
- Vendor dependencies — SaaS tools, contractors, suppliers.
- Data dependencies — datasets, analytics pipelines, third-party data feeds.
- Regulatory dependencies — approvals, compliance sign-offs, licensing.
- Market dependencies — partner ecosystems, integrations, platform policies like app store rules.
A real scenario: a SaaS team plans a feature that needs a compliance sign-off (regulatory), an export from the data team (organizational), and a social platform login (market). All three can slip independently — and any one of them blocks the launch.
The app store example deserves special attention. If your mobile product lives entirely in one store, a single policy change — think privacy rules like Apple’s App Tracking Transparency — can cut your onboarding numbers overnight. That’s dependency risk with a blast radius covering your entire growth funnel.
How to Map Your Dependencies Before They Surprise You
Dependency mapping means drawing what your product depends on — upstream (what feeds you) and downstream (what you feed) — so you can see failure points instead of discovering them during an incident. You can’t manage what you haven’t listed, so step one is simply building a dependency register: a living document, not a one-off workshop artifact.
Start with your last three delayed projects. For each one, ask: what did we wait on? Trace the chain. A delayed checkout feature might reveal it waited on the payments platform team, which waited on a vendor SDK, which waited on a security review. Three links, one of which you controlled.
- List every dependency for each initiative on your roadmap — technical, human, and contractual.
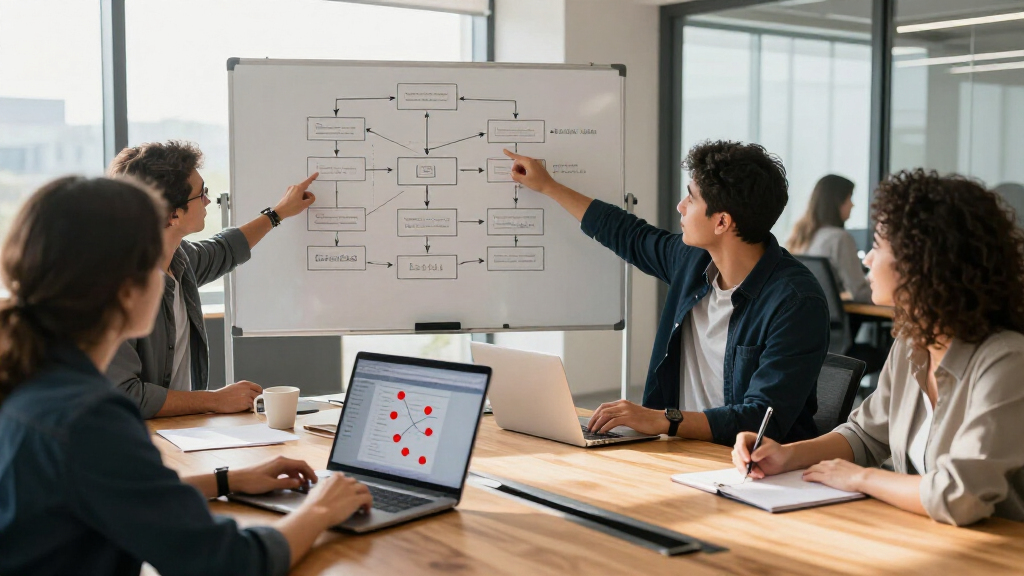
- Draw the graph — a simple boxes-and-arrows sketch works; teams using C4 models or dependency graphs get more precision, but a whiteboard beats nothing.
- Mark the critical path — which dependencies, if delayed, push your launch date directly?
- Score each one — likelihood of failure × impact, plus blast radius (how much of the product it takes down).
- Flag single points of failure — including human ones. If only one person knows how the integration works, your bus factor is one, and that’s a dependency too.
On the technical side, tooling helps: SBOMs (Software Bills of Materials) have become the standard way to inventory the open-source packages inside your build, driven partly by US Executive Order 14028 and the EU Cyber Resilience Act. For organizational dependencies, no tool replaces a quarterly conversation with the teams you depend on.
Scoring Dependency Risk: Small Table, Big Clarity
Not all dependencies deserve equal worry. Scoring them on likelihood, impact, and blast radius turns a vague sense of unease into a ranked list you can actually act on — and a table you can show executives in five minutes.
| Dependency type | Likelihood of failure | Typical blast radius | Best mitigation |
|---|---|---|---|
| Mature open-source library | Low–medium | Build breaks, security exposure | SBOM audits, lock versions, pin patches |
| Niche/abandoned library | Medium–high | Full feature outage | Fork, replace, or vendor it in |
| Single cloud region | Low but real | Everything, during an outage | Multi-region failover |
| Internal platform team | Medium (prioritization risk) | Roadmap slip, not outage | Team APIs, shared roadmap reviews |
| App store / platform policy | Medium | Entire distribution channel | Multi-channel presence, policy monitoring |
| AI model/API provider | Medium (pricing and drift) | Feature quality, cost spikes | Abstraction layer, model portability |
Two lessons from this table. First, internal teams are often the riskiest — not because they fail, but because their priorities shift without notice. Second, the newest entries — AI APIs and models — carry a risk profile older frameworks didn’t anticipate: availability, yes, but also licensing changes and model drift, where outputs quietly degrade or change behavior when a provider updates the underlying model.
Score honestly. A dependency you rate as ‘low risk’ because you don’t want a hard conversation isn’t low risk. It’s unmanaged risk wearing a smile.
Your Mitigation Playbook: Reduce, Protect, Decouple
Once you can see your dependencies, you have three moves: reduce them, protect against them, or decouple from them. Good teams use all three, matched to the risk score.
- Reduce critical-path dependencies first. If a feature needs four external sign-offs to ship, ask whether two would do. Every dependency you remove from the critical path buys back schedule certainty.
- Add contractual protections for vendors. Negotiate SLAs, exit clauses, and data portability before signing — not during the outage. Ask: if this vendor disappeared in 90 days, could we get our data out and keep operating?
- Build fallbacks and graceful degradation. If the recommendations API is down, can your product show a static list? Products that degrade gently lose minutes of quality; products that hard-fail lose customers.
- Introduce abstraction layers. An anti-corruption layer — a thin wrapper around an external API — means that when the provider changes or dies, you rewrite the wrapper, not the product.
- Run regular dependency audits. Quarterly is a good rhythm: technical (SBOM scan), vendor (contract and health review), and organizational (are the teams we depend on still aligned?).
The colors.js incident makes the case for item five vividly. Teams with locked, audited dependencies and CI pinning recovered in hours. Teams pulling whatever ‘latest’ offered spent days untangling transitive packages. Same event, very different Mondays.
One caution: mitigation isn’t free. An abstraction layer adds code to maintain; multi-region failover adds cost and complexity. Every mitigation is itself a tradeoff — apply it where the blast radius justifies it, not everywhere.
Metrics That Keep Dependency Risk Visible After the Workshop
Dependency risk fades from attention the moment the planning workshop ends — unless something measures it. The right metrics make hidden waiting visible week after week, so it shows up in your dashboard instead of your retrospectives.
- Dependency count per initiative — a simple leading indicator. When it climbs, expect coordination cost to climb faster.
- Blocked-item count — how many backlog items are waiting on something external right now.
- Lead time vs. cycle time — the gap between them is roughly time spent waiting on dependencies rather than doing work.
- Bus factor — the number of people who understand each critical dependency. One is a red flag.
For executives, translate these into dates and dollars. ‘We have 14 blocked items’ means little in a board meeting. ‘The checkout redesign slips six weeks because the payments team’s queue is full through March’ means a decision gets made.
Apply the Team Topologies lens here too: when platform teams expose clear team APIs — documented interfaces with owners and roadmaps — the teams depending on them can plan instead of hoping. Organizational design is dependency management by another name.
Build vs. Buy — When a Dependency Is Worth It
The build-vs-buy question is really a dependency-risk question in disguise. Every time you adopt a third-party tool or library, you’re trading engineering effort for dependency risk. Sometimes that’s an excellent trade. Sometimes it’s a slow-motion trap.
Use a risk lens on the decision. Ask three things. How healthy is the thing you’re depending on — an actively maintained library with many contributors is safer than a side project run by one burned-out maintainer. How replaceable is it — can you swap it out in a week, or is it woven through your data model? And how aligned are incentives — a vendor whose revenue depends on your success behaves differently from a free API that exists at another company’s whim.
Open source deserves a specific mention, because incidents like Log4Shell (the December 2021 vulnerability in the ubiquitous Log4j library) showed how widely a single free component can be embedded — and how few teams knew they were running it. That’s exactly why SBOMs went from nice-to-have to regulatory expectation. Adopting open source is usually the right call; adopting it blind is not.
Every dependency is a loan of trust. Audits are the interest payments — small, regular, and much cheaper than default.
When you do buy, negotiate the exit before the entrance: data export, SLAs, and a documented offboarding path. The best time to discover a vendor’s lock-in is never.
Frequently Asked Questions
What’s the difference between dependency risk and general project risk?
General project risk covers anything that could derail delivery — staffing, scope, budget. Dependency risk is narrower: it’s specifically the risk from things your product relies on but doesn’t control, like third-party APIs, vendors, or internal platform teams. Dependency risk is usually a subset of project risk, but it deserves separate treatment because it responds to different mitigations — contracts, fallbacks, and mapping rather than buffers and contingency budgets.
How do I find hidden dependencies in my roadmap?
Start with your last three delayed projects and trace what each one waited on — you’ll surface organizational and data dependencies that never appear in code. On the technical side, generate an SBOM to reveal transitive open-source packages. Then ask each engineer one question: ‘If this feature ships late, what — outside our team — will be the reason?’ The answers are your hidden dependencies.
How many dependencies is too many?
There’s no magic number — the issue is how many sit on your critical path. Because coordination overhead grows non-linearly, an initiative with four or five critical-path dependencies will feel dramatically less predictable than one with two. A practical rule: if a dependency doesn’t change what you ship, accept it; if it can change when you ship, count it, score it, and try to remove it.
How do we manage dependencies on internal teams we can’t control?
Treat internal teams like vendors, but with better communication channels. Establish clear team APIs — documented interfaces with named owners and shared roadmap visibility. Include their capacity in your planning, negotiate priorities early rather than at sprint boundaries, and escalate mismatches with dates, not frustration. Blocked-item metrics make the waiting visible enough that leadership can resolve priority conflicts for you.
What should we do if a critical vendor fails or an API shuts down?
Follow your pre-written fallback: switch to graceful degradation so users see a reduced product instead of an outage, activate any backup provider or cached data path, and communicate honestly with customers about timelines. The recovery speed depends almost entirely on preparation — export paths negotiated in the contract, an abstraction layer isolating the dead API, and a documented runbook. If none of those exist, the shutdown becomes your next quarter’s main project.
What metrics should we track for dependency risk?
Track four: dependency count per initiative (a leading indicator of coordination cost), blocked-item count (waiting made visible), the gap between lead time and cycle time (roughly time lost to dependencies), and bus factor per critical dependency. Review them monthly, and translate them into dates and dollars for executive audiences — ‘six weeks of slip’ gets decisions made where ’14 blocked items’ doesn’t.
Conclusion
If you remember one thing, make it this: dependency risk is manageable only when it’s visible. The teams that survive outages, API shutdowns, and platform policy changes aren’t the lucky ones — they’re the ones who had a register, knew their blast radius, and had already written the fallback plan while everything was calm.
Start small. This week, take your next big initiative and list everything it depends on. You’ll likely find a few surprises. And the next time a stranger’s npm package breaks the internet, you’ll be the team reading about it over coffee — not the one paging the on-call.
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.