TL;DR

Get privacy and security gear delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
Testing network resilience is essential but risky if done improperly. Using isolated environments, automation, and advanced simulation tools allows you to identify vulnerabilities without causing outages. Regular, planned testing keeps your network strong and reliable.
Imagine running a busy online store during a flash sale. Suddenly, your website crashes. The cause? An untested vulnerability in your network. Now, picture having a way to find those weak spots before they turn into full-blown outages. That’s what resilience testing is all about. But here’s the catch: testing can be risky. If you’re not careful, you could cause outages instead of preventing them.
This guide reveals how you can assess your network’s ability to handle failures without interrupting your service. You’ll learn about safe methods, the latest tools, and best practices that keep your network up and running while you test its limits. Whether you manage a small home lab or a complex enterprise network, these strategies will help you spot vulnerabilities early—without the chaos of unexpected outages.
Always create a dedicated, isolated environment that mirrors your production network for testing purposes.
Leverage automation and chaos engineering tools with safeguards to inject failures systematically and safely.
Use simulation platforms—virtual labs or cloud-based—to test real-world failure scenarios risk-free.
Schedule regular resilience tests, especially after major updates, and monitor results continuously.
Document every test, analyze outcomes, and refine your resilience strategies based on findings.
Network Operations · Resilience Field Guide
How to Test Network Resilience Without Causing Outages
Find weak points before users do. Isolated environments, controlled experiments, and clear stop rules help teams test failure response while protecting live service.
Prove the recovery path before a real failure
A network is resilient when it maintains acceptable service through faults and disruptions. Testing reveals whether failover, monitoring, and recovery plans work as expected. Done carelessly, the test itself can interrupt service; done safely, it turns uncertainty into evidence.
Protect continuity
Unplanned downtime can interrupt sales, damage trust, and expose recovery gaps. Simulated failures help teams find weak links before a high-pressure moment.
Test with control
Use monitoring, virtual labs, and incremental experiments to observe response without taking live services offline.
Know the tradeoffs
Simulations may miss real traffic patterns or timing effects. Higher fidelity can improve relevance but takes expertise, time, and resources.
REPORTED OUTAGE REDUCTION
Figures are claims supplied in the source content; they are not a guarantee of outcomes for an individual network.
A SAFETY-FIRST TESTING BALANCE
These bars illustrate the guide’s priorities, not measured scores. Preserve human oversight and stop criteria throughout each experiment.
Mirror production. Keep the test separate.
Create a dedicated staging environment that reflects network configuration, firewall rules, VPNs, critical servers, and representative traffic. A realistic clone makes results more useful; a separated lab keeps failures contained.
Virtual lab
GNS3 and Cisco Packet Tracer can model routers, switches, and servers for scenarios such as link loss or server failure.
Cloud simulation
Separate virtual networks can test at scale with realistic traffic. Secure sensitive data and account for cloud costs.
Production checks
If a live-system test is necessary, use approved scope, low-traffic windows, redundancy, active monitoring, and a rehearsed rollback.
Scope
Choose one failure mode and define success.
Isolate
Use a lab or staging network with clear boundaries.
Inject
Introduce one controlled fault at a time.
Observe
Watch service health, alerts, and recovery behavior.
Improve
Record results and refine the response plan.
Make every experiment repeatable and stoppable
Automation reduces manual variation; chaos engineering deliberately introduces controlled failures to reveal how systems respond. Start with a single component, monitor continuously, and use safeguards that stop or reverse an experiment when critical signals cross a threshold.
Start small
Test one component or dependency at a time. Expand only after the team understands the observed behavior.
Set guardrails
Define abort thresholds, automatic rollback, alert routing, an owner, and a clear stop command before running.
Keep oversight
AI predictions can target likely weak points, but data quality affects results. Review recommendations and validate findings manually.
Match the test to the risk and the question
Each method offers a different balance of realism, containment, and setup effort. Choose the least risky approach that can answer the question—and be explicit about the limits of what it proves.
| Method | Disruption risk | Best for | Watch for |
|---|---|---|---|
| Isolated virtual lab | ✓ Low | Topology, configuration, and failure scenarios | Model fidelity and traffic assumptions |
| Cloud-based simulation | ✓ Low | Scale and repeatable traffic patterns | Data security, cost, and cloud differences |
| Incremental chaos test | ~ Managed | Recovery behavior and dependency discovery | Scope, monitoring, safeguards, and rollback |
| Live production test | ! Higher | Validating behavior a lab cannot reproduce | Approval, timing, redundancy, and stop criteria |
Test regularly. Learn from every run.
Schedule resilience checks quarterly or biannually, and repeat relevant tests after major network changes or updates. Keep a record of the scenario, scope, alerts, recovery time, unexpected behavior, and follow-up actions.
Before the test
Confirm scope, owner, maintenance window if needed, backups, redundancy, monitoring, communication plan, and rollback steps.
After the test
Review logs, distinguish benign anomalies from real faults, assign fixes, and update runbooks. Re-test changed controls to confirm the improvement.
Why Safe Network Testing Matters More Than Ever
In today’s digital landscape, downtime isn’t just inconvenient—it’s costly. Every second your network is down, you lose revenue, damage your reputation, and risk data breaches. That’s why testing your network’s resilience is a top priority. But traditional testing methods—like taking systems offline or pushing them to failure—can cause real outages, especially if done haphazardly.
By testing safely, you avoid these risks. You can simulate failures, identify weak points, and improve your defenses—all without disrupting your users. For example, a financial services firm might run tests during off-peak hours, or use virtual environments to mimic their entire network. This way, they find vulnerabilities before a real crisis strikes.
Recent industry trends show that organizations adopting non-disruptive testing methods reduce unplanned outages by over 60%. That’s a game-changer. It means you get the insights you need without risking your reputation or customer trust. The implications are clear: safe testing not only preserves business continuity but also enhances overall security posture, since it encourages continuous, proactive vulnerability assessment rather than reactive fixes after failures occur. However, it’s important to recognize that these approaches often involve tradeoffs, such as potentially missing some real-world failure nuances or requiring more complex setup, which can demand additional expertise and resources.
As an affiliate, we earn on qualifying purchases.
How to Build a Safe Testing Environment in Your Network
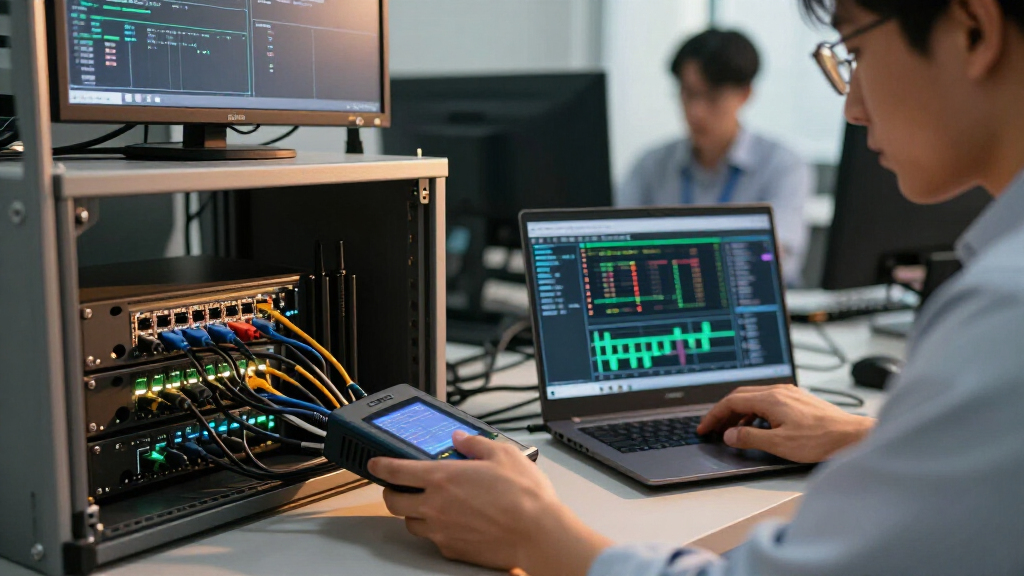
The first step in testing network resilience without causing outages is creating a dedicated, isolated environment that mirrors your live network. Think of it like a sandbox—where you can play and experiment without risking the real thing. You might set up a virtual lab using tools like GNS3 or Cisco Packet Tracer, which simulate routers, switches, and servers with high fidelity.
For example, a small business might replicate their core network in a virtual environment, including their firewall rules, VPN setups, and critical servers. This clone allows them to run failure scenarios, like simulating a server crash or a DDoS attack, without impacting their actual operations. The key here is fidelity—if the test environment doesn’t accurately reflect the real network’s configuration and traffic patterns, the results may not be applicable, leading to a false sense of security or missed vulnerabilities. Therefore, investing time in detailed replication is crucial, even if it demands additional effort upfront.
Another approach is to use cloud-based testing platforms. These platforms spin up virtual networks that are completely separate from your production environment. They enable you to test at scale, with realistic traffic patterns, and without risking outages. However, this comes with considerations around data security and cost, as cloud environments may expose sensitive information if not properly secured.
Key tips include:
- Replicate your network as closely as possible to catch real-world vulnerabilities, understanding that higher fidelity often involves increased complexity and resource investment.
- Use automation to run repeatable tests, reducing human error but also requiring careful scripting and validation to ensure consistency.
- Schedule tests during low-traffic periods or maintenance windows to minimize impact, but recognize that some vulnerabilities only surface under load or specific timing conditions.
This setup ensures you get actionable insights without risking your day-to-day operations. Remember, the goal is to balance thoroughness with safety, understanding that more comprehensive environments can be more complex to manage but yield more reliable results.
As an affiliate, we earn on qualifying purchases.
Leverage Automation and Chaos Engineering Safely
Automation and chaos engineering are your best friends when it comes to testing resilience without causing outages. Automation allows you to run predefined failure scenarios systematically—think of it as a checklist of what to test, and how, without manual intervention. Chaos engineering takes this further by intentionally injecting failures into your system to see how it responds.
For example, a cloud service provider might use a tool like Gremlin to simulate server crashes or network latency. These tests help identify weak points before a real attack or failure occurs. Crucially, these tools can be configured with safeguards—like automatic rollback or alerts—so that if something goes wrong, the system recovers instantly. These safeguards are vital because they prevent minor issues from escalating into outages, but they also introduce tradeoffs: overly aggressive settings might mask real problems or cause unnecessary panic, while too cautious configurations might limit the effectiveness of testing. The key is to find a balance—test enough to uncover vulnerabilities without risking system stability.
Recent advances include AI-powered tools that predict which parts of the network are most vulnerable, then automatically run targeted tests. This proactive approach can uncover hidden weaknesses that manual testing might miss, but it also depends heavily on the quality of data and algorithms, which can produce false positives or negatives. Therefore, combining AI-driven insights with manual oversight improves reliability.
It’s important to understand that while automation and chaos engineering can be powerful, they come with tradeoffs. Over-reliance or poorly configured tests can lead to false positives, unnecessary panic, or even accidental disruptions if safeguards fail. Therefore, balancing thoroughness with caution is vital. Proper planning, incremental testing, and clear rollback procedures are essential to fully realize their benefits without unintended consequences.
Best practices:
- Start small—test one component at a time to understand its behavior and limit potential impact.
- Set thresholds for failures—stop testing if critical systems show signs of instability, and analyze logs carefully to distinguish between benign anomalies and real issues.
- Monitor everything—use dashboards to track responses and catch anomalies early, enabling quick intervention if needed.
This disciplined automation ensures you learn from failures without causing chaos, but it requires ongoing oversight and refinement to remain effective and safe.
As an affiliate, we earn on qualifying purchases.
Use Simulation Tools for Realistic, Risk-Free Testing
Simulation tools are game-changers for testing network resilience safely. They create virtual copies of your network that behave just like the real thing—down to traffic patterns, device behaviors, and failure modes. For instance, Cisco Packet Tracer or GNS3 can emulate entire network topologies, letting you run failure scenarios with no risk to your actual infrastructure.
Imagine a large enterprise that uses simulation to test how a switch failure impacts their entire data center. They simulate the failure, observe how traffic reroutes, and fine-tune their failover protocols—all without touching their live network. This approach helps catch issues early, like misconfigured routing or bottlenecks, before they cause outages. The key advantage is that it allows for testing under diverse conditions without risking operational stability, which is crucial for sensitive environments where even minor disruptions can have significant consequences.
Cloud-based simulators add another layer of realism, allowing you to test at scale with real traffic loads. They’re especially useful for testing complex scenarios like DDoS mitigation or cloud failover strategies. However, it’s important to recognize that simulation isn’t perfect. While it can mimic many aspects of real networks, certain unpredictable behaviors—like user traffic spikes or hardware anomalies—may not be fully replicated. This limitation underscores the importance of combining simulation with real-world testing and ongoing monitoring. This layered approach helps you identify vulnerabilities more accurately and prepare for a wider range of failure scenarios, reducing the risk of surprises during actual incidents.
Practical tips:
- Choose tools that match your network complexity and ensure they are configured correctly to reflect real-world conditions.
- Run multiple failure scenarios—hardware, software, and configuration issues—to cover a broad spectrum of potential problems.
- Compare simulated responses with your expectations and real-world data to identify gaps and improve your resilience plans.
Simulation tools help you find vulnerabilities in a controlled, risk-free environment, giving you confidence in your resilience plan. They also allow for iterative testing—refining configurations and response strategies—without impacting live operations, which is invaluable for continuous improvement.
As an affiliate, we earn on qualifying purchases.
Regular Testing and Monitoring: Keep Your Network Ready
Testing your network’s resilience isn’t a one-time event. It’s an ongoing process—like regular health checkups for your network. The key is to schedule periodic tests, especially after significant changes, updates, or new deployments. For example, after installing new hardware or updating firmware, running a resilience test helps catch new vulnerabilities early.
Monitoring tools like Nagios or Zabbix are essential companions. They provide real-time insights during tests, alerting you to anomalies or failures immediately. Imagine running a simulated DDoS attack in your test environment; monitoring tools can flag unusual traffic spikes, enabling swift responses. This continuous oversight is crucial because it ensures that vulnerabilities are detected promptly, and response strategies are effective under real conditions.
Set clear benchmarks for success—such as acceptable latency or failover times—and track them over time. This way, you create a resilience baseline and can measure improvements or regressions. Regular testing combined with continuous monitoring enables proactive detection of emerging issues, allowing you to adapt defenses before failures escalate. It also helps validate the effectiveness of your mitigation strategies, ensuring they hold up under evolving threats and network changes. For example, a healthcare provider might schedule quarterly tests aligned with maintenance windows, ensuring their critical systems can handle real-world failures without risking patient care. The tradeoff here is resource allocation—consistent testing and monitoring require dedicated effort, but neglecting these practices can lead to overlooked vulnerabilities that might cause outages when most needed.
Remember, consistency is key. Regular testing and vigilant monitoring keep your network resilient and your team prepared for any crisis. While these ongoing efforts demand investment, their payoff is a robust, well-understood network environment capable of withstanding diverse failure modes and minimizing downtime risks.
Frequently Asked Questions
How can I test network resilience without risking downtime?
Use isolated virtual labs, cloud-based testing environments, and automation tools that simulate failures. These methods let you identify vulnerabilities safely, without impacting your live network.What tools are best for non-disruptive resilience testing?
Popular options include network simulators like GNS3 or Cisco Packet Tracer, chaos engineering platforms such as Gremlin or Chaos Monkey, and monitoring solutions like Nagios or Zabbix.Is chaos engineering safe for production networks?
Yes, when carefully planned and controlled, chaos engineering can be performed in production environments. Automated safeguards, monitoring, and incremental testing prevent unintended outages.How often should I perform resilience testing?
Quarterly or bi-annual tests are recommended, with additional testing after significant network changes, updates, or security patches to ensure ongoing robustness.What are the main risks of testing network resilience?
Risks include accidental outages, data loss, or security breaches if tests are poorly managed. Proper planning, safeguards, and monitoring help mitigate these risks effectively.Conclusion
Safely testing your network’s resilience isn’t just smart—it’s essential. By using virtual environments, automation, simulation tools, and a disciplined approach, you can uncover vulnerabilities without risking outages. Think of it like a fire drill—better to practice in a controlled setting than face chaos during a real emergency.
Remember, resilience isn’t a one-time achievement; it’s a continuous process. Regular testing and vigilant monitoring keep your network ready for whatever comes next. When you treat resilience like an ongoing habit, outages become less of a nightmare and more a manageable risk.
So, set your testing plan today. Your network—and your users—will thank you for it.
Halloween Picks
halloween
As an affiliate, we earn on qualifying purchases.