TL;DR

Get privacy and security gear delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
A network baseline describes the expected patterns in traffic, performance, devices, and service use across the times and places that matter to you. Comparing current measurements with that reference helps you tell routine variation from a change worth investigating, but a deviation alone does not prove a fault or an attack. Start with reliable measurements tied to user experience, capture representative cycles, and review the baseline as your network changes.
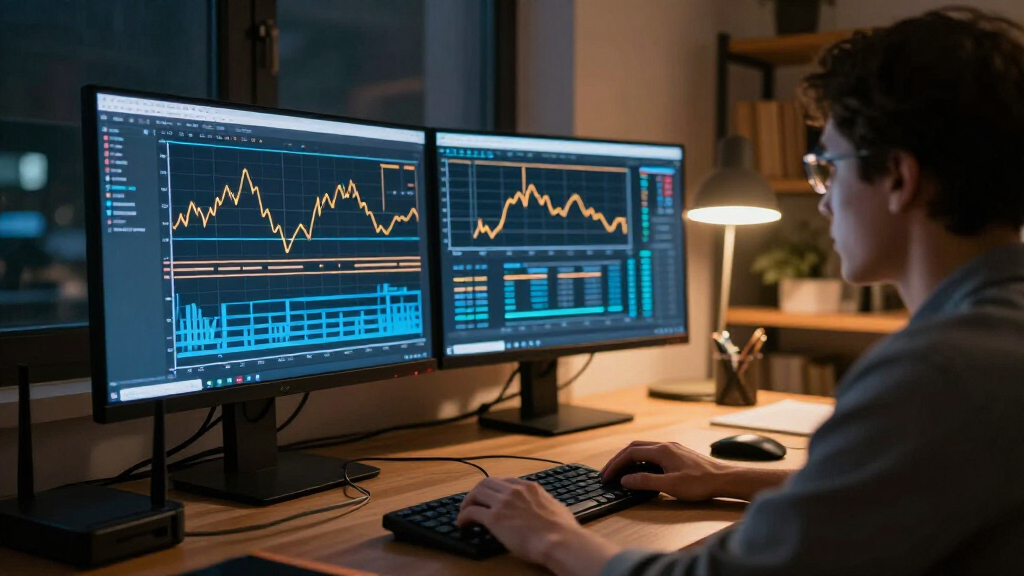
A burst of network traffic at 2 a.m. can mean trouble. It can also mean your scheduled backup is doing exactly what you asked it to do. Without a picture of the network’s usual rhythms, the alert gives you a number but not much help deciding what that number means.
Network monitoring starts with knowing normal because every useful alert needs context. A baseline describes the traffic, response times, devices, and schedules you typically see. In this guide, you’ll learn what to measure, how long to observe, and how to respond when a pattern changes. You’ll also see where a baseline can help with security, and where it cannot.
Your home, school, small office, or cloud service has its own daily pulse. Think of a baseline as a map of that pulse: useful for spotting a new bump in the road, but never a promise that every road is safe.
A baseline describes expected network behavior across relevant times, places, workloads, and services.
Start with availability, latency, packet loss, or link use that connects to a real user experience question.
Observe long enough to include weekly, monthly, or seasonal cycles that matter to your network.
Treat deviations as clues; confirm duration, user impact, change records, and independent measurements before acting.
Review the baseline when your network or monitoring coverage changes, and do not let recurring problems redefine healthy behavior.
Why Network Monitoring Starts With Knowing Normal
A burst of traffic at 2 a.m. could be trouble—or a scheduled backup doing exactly what you asked. A baseline gives alerts the context to tell routine variation from a change worth investigating.
Traffic, performance, devices, and service use
Workload and service shape what is routine
Capture the cycles that matter to your network
Check impact, duration, and measurement quality
A baseline turns numbers into clues
Normal belongs to your environment. The same traffic level can mean very different things at different times or in different services.
Know the rhythm
Evening streaming, school-day peaks, end-of-day file syncs, and overnight backups can all be expected patterns.
Compare like with like
Compare a busy Tuesday morning with other Tuesday mornings, and consider location, workload, and service impact.
Set a separate goal
A baseline describes what has happened. It does not certify that familiar performance is good, healthy, or secure.
A few quiet days can miss weekly or month-end cycles. A scheduled backup or workload may then look anomalous simply because the baseline never saw it.
Start with what users feel
Choose a question first, then collect the few signals that can help answer it. More counters do not automatically mean more clarity.
Record where each signal comes from and what it covers. Missing telemetry, clock differences, faulty sensors, or changed monitoring coverage can make ordinary activity look strange.
A practical baseline, step by step
Keep the first effort small enough to explain, review, and update as the network changes.
Pick a question
Choose a service or link people rely on.
Choose measures
Track only signals that can answer it.
Cover real cycles
Include busy and quiet periods, workdays, and relevant longer cycles.
Log known events
Note maintenance, new devices, software, and scheduled jobs.
Check before tuning
Confirm steady data coverage and recurring patterns before setting alerts.
Context narrows the search
When a pattern changes, compare timing and impact before deciding where to investigate.
6 p.m. file sync
A design office link fills up as laptops sync files at the end of the day. The sync finishes quickly and users have left. The pattern may be expected for that workload and time.
10 a.m. slowdown
A similar spike during client calls could affect users. Check duration, latency, packet loss, the service experience, and planned changes before drawing a conclusion.
One baseline cannot answer every question
Use signals matched to the decision. Service health and security monitoring overlap, but they are not interchangeable.
Is the network serving users?
Utilization, latency, packet loss, availability, and application response help assess performance and guide troubleshooting.
Is behavior unexpectedly different?
Unexpected destinations, unusual connection patterns, or shifts in device behavior may warrant security review. A performance baseline alone is not a complete detection system.
Compare, confirm, then respond.
When an alert appears, verify that the measurement source is working. Check how long the change lasted, whether users were affected, what planned work occurred, and whether an independent signal supports the finding. Review the baseline when devices, services, sites, or monitoring coverage change. Keep recurring problems visible so they do not quietly become the definition of healthy.
A baseline turns network numbers into useful clues
Network monitoring starts with knowing normal because the same measurement can be routine on one network and unusual on another. A baseline is a reference for expected behavior, including the ways that behavior shifts by time, location, workload, and service. It gives you a point of comparison when traffic, response time, or device activity changes.
Say your home internet slows every evening when everyone streams video. A jump in bandwidth at 8 p.m. may fit that familiar pattern. If the connection instead slows at noon while your household is away, the change deserves a closer look. The measurement alone does not tell you why it happened; the time and your network’s usual routine help shape the next question.
A baseline can include link utilization, latency, packet loss, availability, connection counts, application traffic, and device resource use. You do not need to track everything at once. Start with measures connected to a problem you want to spot, such as whether a video call service slows when the office connection gets busy.
A baseline describes what has happened; it does not certify that the network is healthy or secure. If your connection has been slow for months, a baseline may capture that poor performance as familiar. Compare it with user needs and service goals before treating a familiar pattern as an acceptable one.
As an affiliate, we earn on qualifying purchases.
Your network’s schedule explains many alarming spikes
Routine variation and meaningful change can look alike until you know the network’s schedule. Normal behavior shifts with working hours, school bells, backups, software updates, and seasonal demand. A useful baseline captures those rhythms so an alert can be judged against what usually happens at that time.
Imagine a small design office where laptops sync large files to cloud storage at the end of each workday. The link fills up around 6 p.m., but staff are already leaving and the sync finishes quickly. A similar spike at 10 a.m. could interrupt a client video call. The bandwidth number may match; the timing and service impact change what it means.
A short observation window can miss cycles that happen weekly, at month end, or during a busy season. A school network may have quiet weekends and crowded weekday mornings. A shop may see traffic climb before holidays. Monitor long enough to capture the cycles that matter, and write down known events such as payroll runs or scheduled maintenance.
Normal is specific to your environment. Two offices with the same routers can have different patterns because their users, applications, and schedules differ. Cloud services and remote work add more variation across location and time. Treat the baseline as a local reference, not a universal rulebook.
network performance baseline software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Start with measurements that show what users feel
The most useful network baseline begins with measurements tied to user experience and likely failure points. Availability tells you whether a service or link responds; latency shows how long a response takes; packet loss indicates whether data fails to arrive; link use shows how much capacity is busy. Together, these measures offer a practical first view.
For example, if staff say that calls sound choppy every Tuesday morning, compare packet loss and latency during that period with quieter hours. If those measures rise together, congestion or a link issue may be part of the story. If they stay steady, check the calling service, devices, or wireless coverage as well. A baseline helps narrow the search; it does not diagnose every cause.
Choose measures based on a question, not because a dashboard offers them. If you want to know whether backups slow browsing, measure link use alongside the response time of a key service. If you want to notice when a printer disappears, its availability may matter more than overall bandwidth. Starts with knowing what you need to answer is a better rule than collecting every available counter.
Measurement quality matters too. A sensor that misses data, a clock that differs from other devices, or a change in monitoring coverage can make ordinary activity look strange. Note where each measurement comes from and what it includes. When an alert appears, check that the instrument was working before drawing conclusions about the network.
As an affiliate, we earn on qualifying purchases.
Build a baseline you can explain and maintain
To build a useful network baseline, choose a question, collect representative measurements, record known events, then review unusual patterns before setting alert rules. A baseline works best when someone can explain what it covers and why a pattern counts as familiar. Keep the first effort small enough to manage.
- Pick a service or link. Start with the office internet connection or the service users rely on most.
- Choose a few relevant measures. Track availability, latency, packet loss, or utilization according to the question.
- Cover meaningful time periods. Include busy and quiet hours, workdays and weekends, and known scheduled jobs.
- Record planned changes. Note maintenance, new software, added devices, or moves that could affect measurements.
- Review before tuning alerts. Check recurring patterns and confirm that the data source has steady coverage.
Consider a small clinic measuring the connection used for appointment calls. Staff might note that a secure backup runs overnight and record response time during clinic hours for several weeks. That gives them a clearer comparison when calls lag at 10 a.m. than one day of readings would.
Some monitoring tools use analytics or machine learning to flag deviations from learned behavior. These can reveal patterns that fixed limits miss, but they depend on representative data and still need human review. A new application or a faulty sensor can confuse them. Static thresholds remain easy to understand for clear limits; many teams use both approaches and check alerts against operating context.
network security monitoring system
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Treat an unusual reading as a prompt to investigate
A deviation is a signal to investigate, not proof of a problem. A traffic jump, new connection pattern, or latency spike tells you that a measurement differs from the reference. It does not establish whether the cause is a fault, planned work, changing demand, a sensor issue, or unwanted activity.
Suppose a small business sees a sudden increase in traffic to its cloud storage service. The owner recently added a new laptop, and the device is syncing a large archive for the first time. That planned setup may explain the increase. If traffic continues after the sync should have finished, or appears alongside unusual device behavior, the owner has a reason to look more closely.
Check whether the change lasts, whether a critical service is affected, and whether independent measurements show the same pattern. Compare what you see with user reports and recent change records. If only one sensor reports a spike while other sources remain steady, check the sensor and its coverage before escalating the alert.
Performance and security monitoring use different clues. Utilization, latency, packet loss, and availability help you assess service health. Unexpected destinations, unusual connection patterns, or changes in device behavior may matter for security. A performance baseline alone cannot identify every attack or establish intent; combine network observations with endpoint, identity, and other relevant security context.
Keep the baseline current without rewriting history
A baseline needs review whenever your network or its measurements change. New applications, staff, sites, equipment, cloud services, and security policies can all alter expected behavior. A reference that once fit your office may stop describing it after a major change in how people work.
For example, a company may move file sharing to a cloud platform and add remote staff. Traffic once concentrated on the office network now comes from different locations and services. If the monitoring view covers only the office link, it may miss the new pattern. Include relevant cloud, endpoint, application, and network measurements where they answer a real operational question.
Review the baseline periodically, and after changes that affect traffic or monitoring coverage. Keep enough history to compare before and after a change, and document planned work that explains a new pattern. Avoid automatically absorbing every unusual event into “normal.” A recurring error should not become acceptable simply because it repeats.
Collect enough useful context to answer your questions without drowning in dashboards, storage costs, or alerts. If an application-level measure does not help you understand a service problem, you may not need it. The baseline is most useful when it stays representative, understandable, and connected to decisions people can act on.
Frequently Asked Questions
What does “normal” mean for a network?
Normal means the expected range and pattern of behavior for a particular network, including changes by time, location, workload, and service. A busy link during a scheduled backup may fit one network’s routine and surprise another’s.
How long should I monitor before setting a baseline?
Monitor long enough to capture the cycles that shape your network. A few quiet days may miss weekly jobs, month-end work, or seasonal demand, so a school or shop may need a longer view than a steady home connection.
Which metrics should I baseline first?
Start with availability, latency, packet loss, and link utilization when they relate to a service people use. Add application, flow, or device measurements when they help answer a specific question, such as whether backups slow calls.
Can a baseline help detect a cyberattack?
A baseline can help surface unusual destinations, connection patterns, or device behavior, but unusual activity does not prove an attack. Pair network observations with endpoint and identity context, and treat the change as a reason to investigate.
How do I avoid false alerts?
Use representative measurements, account for scheduled work, and tune alerts around meaningful service impact. When an alert repeats, check whether the pattern is planned, whether the sensor is reliable, and whether the underlying activity still deserves attention.
Conclusion
Remember this: a network alert becomes useful when you can compare it with a trustworthy picture of ordinary behavior. Pick one service people rely on, measure a few things that affect their experience, and capture the schedules and changes that shape its traffic. Review the results before deciding what deserves an alert.
A baseline is a window into your network’s daily pulse. Keep that window clear, and a strange flicker is easier to spot.
Evergreen bestsellers Picks
bestsellers
As an affiliate, we earn on qualifying purchases.