TL;DR

Get privacy and security gear delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
Heat, dust and power problems can damage equipment, interrupt digital services and disable security tools, making physical infrastructure part of cyber risk. You can reduce that risk by monitoring conditions, maintaining backup systems, securing facility controls and practicing recovery with IT, facilities and security teams.
A server can lose its cool long before anyone notices a security alert. A blocked filter, a warm equipment closet or a flickering power supply can push a digital service toward an outage, even when every password is strong.
That is why cyber risk depends on physical conditions as well as software and accounts. Heat, dust and unreliable power can interrupt systems, knock out monitoring and make recovery harder. You will see how these problems connect to everyday security, what to check first and how to prepare without treating every maintenance issue like an attack.
Treat heat, dust and unstable power as cyber risk factors when they can interrupt critical digital services or security controls.
Map important services to their real dependencies, including cooling, power, networks, facility controls and recovery staff.
Test backup power and data restoration under realistic conditions; a running generator or completed backup job alone does not prove recovery will work.
Coordinate IT, facilities and security teams so they can investigate faults and restore services without unsafe workarounds.
Set safeguards according to the impact of downtime: a short interruption affects a small office differently from a clinic, factory or utility.
Infrastructure • Availability • Resilience
What Heat, Dust and Power Have to Do With Cyber Risk
Digital services depend on physical conditions. Heat, dust and unstable power can damage equipment, interrupt operations and disable security tools. A fault is not automatically an attack, but its effects can put data, service and recovery at risk.
Small facility faults can create outsized digital consequences
Physical failures can interrupt services, weaken monitoring and pressure people into rushed workarounds. The security impact depends on what the affected equipment supports.
Heat builds quietly
Servers, switches and controllers produce heat. Failed fans, blocked vents or clogged filters can trigger slowdowns, shutdowns or lasting damage. A shutdown protects hardware, yet the service it supports may still go offline.
Dust clouds the picture
Dust can obstruct airflow and affect industrial sensors. A misleading reading may shape an operator’s decision. Compare unusual readings with physical inspection or another sensor before assuming the displayed state is accurate.
Restarts disrupt trust
Outages, voltage dips and overloaded circuits can interrupt services or restart equipment unexpectedly. Teams may need to check which records are current and whether authentication and monitoring returned correctly.
“A physical fault is not automatically a cyberattack. The risk comes from how it interrupts, amplifies or conceals digital problems.”
Incident response principleFollow the chain from physical condition to service impact
Availability is part of cybersecurity. Emergency workarounds can also create confidentiality or data integrity risks if they bypass safeguards or leave records unreconciled.
Closet switch, blocked vent
A warm, dusty room can cause a network switch to drop connections. Staff under pressure may send files through personal email or use an unapproved hotspot. Check for these workarounds after service returns.
Clinic, storm outage
Lights may return before storage and authentication. Paper processes can keep care moving, but clear instructions are needed to record updates and reconcile them later without conflicting patient records.
Start with a task people need to perform
Two services that look separate may depend on the same circuit, room, network link or recovery staff. Mapping shared dependencies exposes single points of failure before an outage.
Choose a service
Pick a real task: card payments, stock management, appointment scheduling or patient records.
Trace what it needs
List devices, power, network links, cooling, facility controls and relevant outside providers.
Find shared points
Check whether other critical services rely on the same room, circuit, link or people.
Plan the fallback
Define how to continue work, restore service and reconcile records when systems return.
Make recovery a tested team capability
Choose protections according to the consequences of downtime. A short interruption affects a small office differently from a clinic, factory or utility.
Monitor conditions
Keep vents clear and watch for unusual warmth, noise, sensor readings and recurring hot spots.
Maintain facility systems
Schedule cleaning and repair; secure access to building controls and connected operational technology.
Test backup power under load
Verify runtime across power equipment, connected systems, alerts and the people restoring service.
Prove restoration works
Restore data and services in realistic conditions. A completed backup job alone does not prove recovery.
Coordinate response
Bring IT, facilities and security together to investigate faults and avoid unsafe workarounds.
Set priorities by impact
Reserve backup capacity for services where interruption affects safety, essential work or recovery.
How Heat and Dust Can Turn a Small Fault Into an Outage
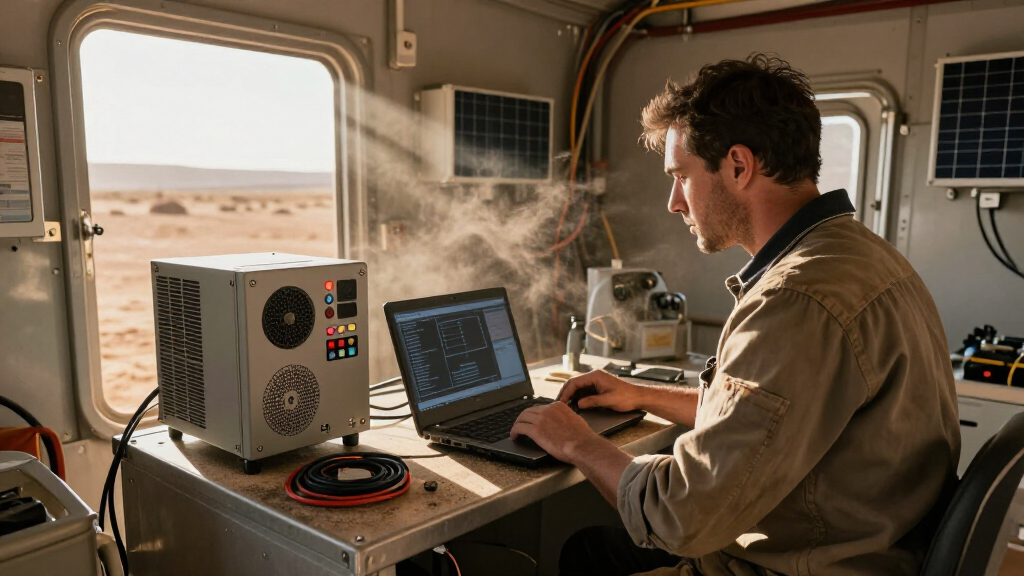
Heat and dust can raise cyber risk by making digital equipment fail or behave unpredictably. Servers, network switches and industrial controllers produce heat as they run, and they rely on airflow to carry it away. When a fan fails or a filter clogs, equipment may slow down, shut itself off or suffer lasting damage. These protections limit hardware damage, but a shutdown can still make a business function unavailable. The security consequence depends on what the equipment supports: a spare office printer may be an inconvenience, while a network switch connecting identity services and monitoring tools can leave many systems harder to manage at once.
Think of a small office with its network switch tucked into a closet beside a dusty printer. The door stays closed, boxes block the vent, and the room grows stuffy by mid-afternoon. The internet drops during a client call. That outage may have nothing to do with an attacker, but staff might move files to personal email or switch to an unapproved hotspot to keep work moving. The physical fault can therefore create pressure to bypass safeguards, and a workaround adopted in haste may persist after service returns unless someone checks for it.
Dust can also affect sensors and machinery in connected industrial settings. A sensor that gives unreliable readings can make software display a misleading picture of what a machine is doing. Operators may respond to the displayed reading, so the danger is not only damaged equipment but decisions made from inaccurate information. That does not make every dusty fan a security incident. It does mean maintenance, monitoring and incident response should account for the condition of equipment, not just what appears on a screen. Comparing an unusual reading with physical inspection or another sensor can help distinguish a real operating change from a faulty measurement.
For a small team, start with a simple walk-through: check that vents are clear, look for unusual warmth or noise, and note where critical network equipment sits. A fan rattling like a loose coin is a useful clue. Facilities staff can help determine whether equipment needs cleaning, repair or better airflow. Keep a record of recurring hot spots or faults: a single warm day may be temporary, but a pattern can show that the room or equipment placement needs a lasting fix.
As an affiliate, we earn on qualifying purchases.
Why a Power Problem Can Become a Cybersecurity Problem
A power problem becomes a cybersecurity concern when it interrupts critical services, security tools or safe recovery. A blackout is usually a physical event, but the effect can spread across data, networks and the people who protect them. A voltage dip or overloaded circuit may also restart equipment without the clean shutdown an organization expects. When systems return in a different order or with incomplete state, staff may not know which records are current or whether monitoring is working. That uncertainty can delay recovery even after electricity is restored.
Consider a medical clinic during a storm. Lights come back quickly, but the network storage and authentication service take longer to recover. Staff may need patient records while the help desk is dealing with several systems at once. A paper process can keep care moving, but the clinic needs clear instructions about how to record updates and reconcile them later so information stays accurate. The tradeoff is speed versus consistency: a fallback that is too cumbersome may be ignored, while one without a reconciliation step can create conflicting records that affect later care.
Backup power can buy time, but it is not magic. A generator that starts during a monthly check may still fail under load, and an uninterruptible power supply with an exhausted battery may keep a switch running for only a few minutes. Backup capacity also has limits: powering every device can be costly and may drain support for the services with the greatest consequences. Testing should cover the whole chain: power equipment, connected systems, alerts and the people who restore service. A test under realistic load can reveal whether the available runtime is enough for an orderly shutdown or a transition to another source.
When you review a power plan, ask which systems need uninterrupted power, how long they need it and what happens when backup power runs out. Include network devices and security monitoring where they support critical operations. The answer will differ between a small design studio and a water treatment facility, because the risk depends on the service and the consequences of downtime. Prioritizing by impact helps direct limited backup capacity toward services where interruption could affect safety, essential work or the ability to recover other systems.
As an affiliate, we earn on qualifying purchases.
How to Map the Physical Dependencies Behind Your Digital Services
Map each important digital service to the physical things it needs to keep working. A backup file is not useful during an outage if the power, network, cooling or recovery team is unavailable. A dependency map helps you find those gaps before an incident turns into a scramble. It also reveals shared points of failure: two services may look independent on paper but rely on the same circuit, room or network link. That matters because one fault can then interrupt both and overwhelm the same people needed to restore them.
- Pick a critical service. For a small retailer, that might be card payments or the stock system; for a clinic, appointment scheduling or access to patient records. Start with a service people need to perform a real task, rather than with a list of equipment.
- List the dependencies. Note the devices, power sources, network links, cooling and facility controls the service relies on. Include outside providers where they matter. This makes assumptions visible, such as a hosted application that still depends on a local router or a building system managed by a separate vendor.
- Ask what happens if each dependency fails. Estimate how long the service can be down and what safe fallback staff can use. A paper form may work for a few hours if someone knows how to reconcile it later. Consider what the fallback costs in time and accuracy, too; a plan that preserves access but creates duplicate or incomplete records may shift the problem into recovery.
- Assign owners and practice. Decide who from IT, facilities and security responds, then walk through a realistic interruption together. Shared ownership helps prevent delays where one team sees a building fault and another sees a service outage but neither has enough context to connect them.
For example, an office may discover that its entry system, Wi-Fi and network closet share one circuit. That arrangement may be acceptable for a low-impact space, but it deserves attention if staff need the network for emergency communication. Write down what people can do during downtime, including how they will protect records and regain access. Then decide whether separating the circuit, adding backup power or improving the fallback process is proportionate to the consequence of losing all three services together.
This exercise does not need a costly diagramming tool. A shared page that names systems, dependencies, owners and fallback steps can reveal who needs to fix each gap. Review it when you change equipment, move rooms or add a connected service. Keeping it current matters because an outdated map can create false confidence: teams may plan around equipment or responsibilities that have since changed.
dust filters for data center equipment
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
What Cloud Services Change—and What They Still Depend On
Cloud services move some infrastructure work to a provider, but they still depend on physical power, cooling, networks and data centers. A small business can avoid maintaining its own server room by using a hosted email or accounting service. That can reduce its local cooling and backup-power burden, but it does not remove every dependency. The business also relies on the provider’s resilience, its own internet connection and the account settings that control access. Moving infrastructure shifts some responsibilities and concentrates others, so the service agreement and the team’s own recovery choices still matter.
Imagine a team whose files are safely stored online. During a local outage, staff may still lose access if the office router and mobile network are both unavailable. Or the provider may have an interruption while the business has no tested way to reach its records or serve customers. Cloud storage is useful, but availability depends on the complete path between the person, network and service. A highly available provider cannot solve a local connectivity failure, and a second connection will not help if staff have no secure way to use it.
When you choose a provider, review its published resilience and recovery information, and understand what your own team must configure. Check whether you can export or restore important data, who manages account access and what your fallback looks like if a service is unavailable. Avoid assuming that the provider handles every part of recovery. A backup or export can add control, but keeping copies also creates work: they need protection, a known owner and a restore process that does not depend on the unavailable service.
There is also an energy trade-off. Efficient buildings and cooling systems can reduce waste, while critical services still need suitable environmental controls and backup plans. The right balance depends on the service and its impact. A personal photo archive and a logistics dispatch system do not need the same recovery arrangements. For a low-impact service, accepting a longer interruption may be reasonable; for a service with immediate operational consequences, stronger redundancy may justify its added cost and complexity.
As an affiliate, we earn on qualifying purchases.
How to Prepare Without Treating Every Fault Like an Attack
Prepare for physical failures as operational risks, and investigate suspicious signs with the same care you bring to digital alerts. A hot server room is usually a maintenance concern, not proof that someone interfered with the cooling system. Still, an unexpected change to a building control system or a failure that coincides with unusual account activity deserves a coordinated look. Treating every fault as an attack can waste response time and damage trust in alerts; dismissing every fault as routine can miss evidence. A clear process lets teams act on what they observe without claiming a cause before they have evidence.
For instance, a warehouse loses cooling after a storm. Facilities sees a failed unit, while IT sees network equipment restarting. Those observations can point to a straightforward outage. If system logs also show an unapproved change to a network-connected controller, security staff should preserve relevant records and follow the organization’s incident process rather than guessing at the cause. Keeping a timeline of physical observations and system events helps teams compare accounts and decide whether the fault is isolated or part of a wider pattern.
- Monitor the basics: temperature, humidity where relevant, power status and equipment alerts. Trends can show gradual deterioration before a shutdown, but too many low-value alarms can obscure the readings that need action.
- Maintain and test: filters, fans, backup batteries, generators and recovery procedures. Planned checks take time and can briefly disrupt operations, so schedule them around service needs and record whether they achieved the expected result.
- Limit control access: keep building and industrial systems restricted to approved accounts and networks. This reduces opportunities for unauthorized changes while preserving access for the staff and providers who need to maintain those controls.
- Coordinate response: give facilities, IT and security teams a shared contact path and clear roles. Early coordination helps each team supply the evidence the others cannot see, such as room conditions, device logs or access changes.
A modest office can begin with a calendar reminder to inspect vents and test backups, plus a written outage contact list. A larger organization may need redundancy and formal incident playbooks. Match safeguards to likely impact, and make sure people can report a physical fault without having to decide whether it is “cyber” first. The goal is to make reporting easy and investigation proportionate, so ordinary maintenance gets handled promptly and genuine warning signs are not lost.
Why Recovery Plans Need More Than a Backup Copy
A backup helps only if you can restore trusted data and run the systems it depends on. Recovery includes power, cooling, network access, staff and a clear order for bringing services back. Without those pieces, a clean backup may sit untouched while a business remains offline. The order matters because some services rely on others: restoring an application before its authentication or network dependencies may add confusion without making the service usable.
Picture a manufacturer restoring its scheduling system after a disruption. The database copy is intact, but the server room still lacks reliable cooling and the factory network is not ready. Restoring everything at once could create more confusion. A recovery plan should name which service comes first, who confirms the restored data is trustworthy and how staff will operate while systems return. Confirming trust matters because a technically successful restore can still reintroduce incomplete or corrupted information if the team does not know which copy to use.
Test the plan in a way that fits your operations. A small organization might restore a sample set of files and confirm that a key application opens. A hospital or utility may need more extensive exercises that involve teams and dependencies. In either case, record how long each step takes and what stopped the team. A test that exposes a delay is useful evidence; a test that only confirms a backup job ran is not enough. The results can show whether recovery targets are realistic and whether the extra cost of faster backups, spare equipment or alternate facilities is justified by the service’s impact.
Ransomware and other disruptive events have made continuity planning more visible, but the same preparation helps with storms, failed cooling and accidental power loss. Keep recovery copies protected from routine account access, and rehearse how you will communicate when normal systems are down. That calm rehearsal is far less stressful than trying to invent a plan beside a dark equipment rack.
Frequently Asked Questions
How can heat or dust cause a cyber incident?
Heat and dust can cause equipment to slow down, shut off or give unreliable readings, which may interrupt digital services. The disruption can also lead staff to use rushed workarounds that weaken data handling or access controls. A physical fault is not automatically an attack, but its effects belong in cyber planning.
Is a power outage really a cybersecurity issue?
It can be, when it disables important services, monitoring or recovery systems. The outage itself may have a physical cause, but the impact can affect data availability and safe operations. Plan for the services that need power and test how they recover.
Can an attacker deliberately interfere with cooling or power?
In some settings, a person with access to connected building or industrial controls could disrupt operations. Many such problems are accidental or weather-related, though, so avoid assuming malicious intent from a failure alone. Investigate unusual system changes alongside physical evidence and follow your incident process.
Does moving services to the cloud solve physical infrastructure risk?
No. A cloud provider operates the data center, but the service still needs electricity, cooling, networks and working connections from your users. Review provider resilience and understand your own responsibilities for data access, recovery and fallback operations.
What should a small organization do first?
Choose one important service and list its dependencies: equipment, power, network, cooling and people. Clear vents, keep up with basic maintenance, test an important backup and write down who responds during an outage. Those steps give a small team a useful starting point without a large infrastructure budget.
Who should own this work: IT, facilities or security?
They should coordinate, because digital services rely on both technology and the building around it. Facilities can spot environmental problems, IT can explain system dependencies, and security can help protect access and guide incident handling. Give each team a clear role and a shared way to raise concerns.
Conclusion
Keep the physical conditions behind your digital services in view. Clear airflow, maintained backup power, restricted access to facility controls and a practiced recovery plan can prevent a small fault from becoming a long outage. Start with one critical service and ask what it needs to keep working.
Cyber resilience is built in quiet places: a clean filter, a tested battery and a team that knows what to do when the lights flicker.
Halloween Picks
halloween
As an affiliate, we earn on qualifying purchases.